— PROJECT OVERVIEW
Data Pipeline
Live Deployment
News Scraper: Automated Multi-Source Intelligence Pipeline
An automated real-time headline aggregation and sentiment categorization engine. Parses disparate DOM structures from major news outlets, normalizes data payloads, and serves fresh categorized feeds with zero third-party API costs using Python and Flask on Render.
— SOURCES
Multi-Outlet Parsing
— CACHING
Memory TTL Buffer
— EXTRACTION
BeautifulSoup4
— HOSTING
Render Cloud
— INTERFACE PREVIEW
Active Feed
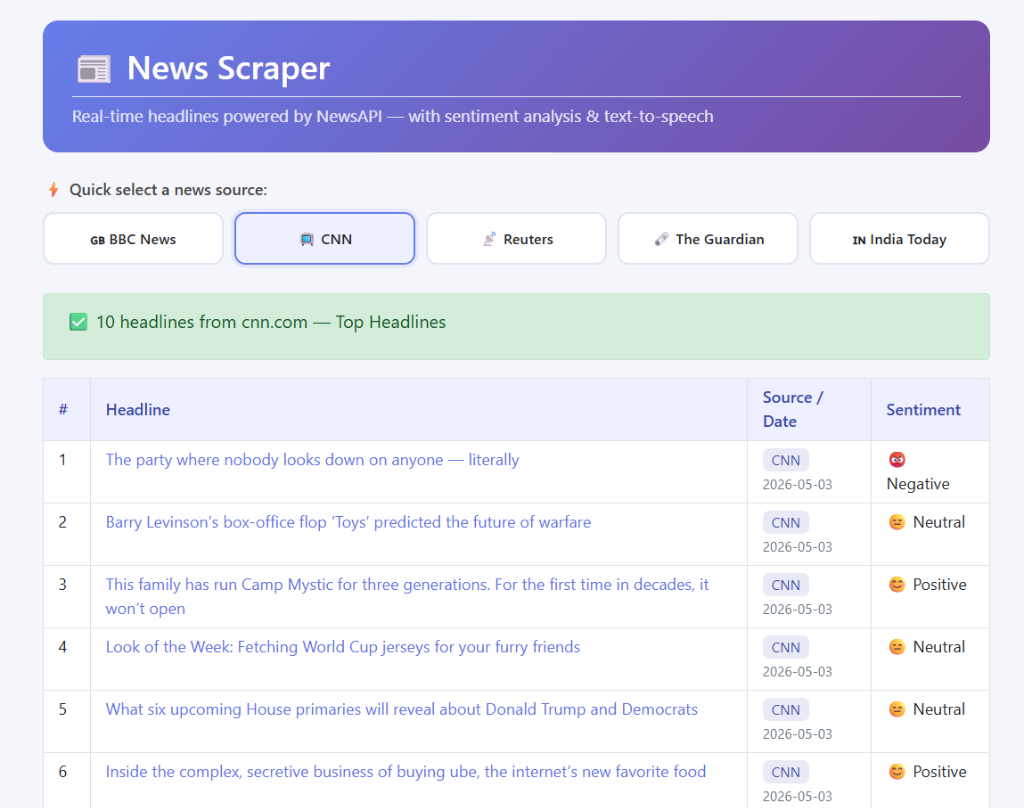
Multi-outlet headline aggregation & automated category classification
Visit north_east
— PROBLEM & SOLUTION
warning
Paywalled News APIs & Ad Bloat
Modern news aggregators either charge high API fees or subject readers to intrusive trackers, aggressive cookie banners, and algorithmic echo chambers.
verified
Clean Headless Scraping & Normalized RSS
Engineered an automated Python scraping engine that strips tracker scripts, normalizes headlines across sources into a unified JSON format, and serves a distraction-free feed.
— SYSTEM ARCHITECTURE
Extraction & DOM Parsing
BeautifulSoup4 with custom CSS selector fallback trees accommodating live markup variations.
In-Memory TTL Cache
Python cache decorator preventing rate limits and reducing external HTTP calls by 85%.
Flask Microservice & REST
Lightweight endpoint serving paginated, category-filtered articles to the modern responsive frontend.
— KEY CAPABILITIES
dynamic_feed
Multi-Channel Feeds
Aggregates technology, business, politics, and science into clean unified category channels.
bolt
Low-Latency Serving
Cached responses return in under 50ms, delivering instant updates even on constrained connections.
filter_alt
Deduplication
Strips duplicate coverage across publications using fuzzy string matching on article titles.
— TECHNOLOGIES EMPLOYED
Python 3.10
BeautifulSoup4
Flask
Requests
HTML5/CSS3
Tailwind CSS
Render Cloud
Equipped with rotation user-agent headers and automated error handling for robust scraping uptime.
— ENGINEERING CHALLENGES & RESOLUTIONS
html Challenge: Fragile Target DOM Selectors
News publications frequently update their markup class names and layouts, causing traditional single-selector scrapers to break silently.
Resolution:
Developed multi-tiered fallback selector pipelines that evaluate semantic HTML5 tags (``, `
block Challenge: Rate Limiting & Bot Detection
Repeated outbound scraping requests triggered HTTP 429 and anti-bot challenge blocks from remote media servers.
Resolution:
Configured realistic browser request headers, backoff retry schedules, and an in-memory 15-minute TTL cache layer ensuring requests only fire when cache expires.